Engineering
e6data’s Architectural Bets: our Head of Engineering’s conversation w/Pete at Zero Prime Podcast
By e6data Team
Our founding engineer and Head of Engineering, Sudarshan, recently went on the Zero Prime podcast and unpacked the internals of our compute engine.
Listen to the episode: Apple Podcasts · Spotify
“We don’t treat object stores like cold storage. And we don’t think your planner should be the bottleneck in a high-QPS workload.”
Sudarshan, Founding Engineer, e6data
It’s a story of breaking away from the driver-executor model, rethinking scheduling for the object-store era, and why atomic, per-component scaling actually matters.
The Real Problem (2025 edition)
Everyone says “compute and storage are decoupled.” Not really.
You scale the cluster because some ad-hoc queries spike.
That 10% of your workload defines your baseline cluster size.
Your scheduler doesn’t react in real-time, so you over-provision just in case.
You get 10% more queries, and you’re forced to double your warehouse size.
Today’s data infra ≠ Today’s compute requirements.
Our Architectural Decisions
We are building e6data by imagining a new playbook. No central coordinator. No one mega-driver. No lock-in to a single table format. Here’s the breakdown:
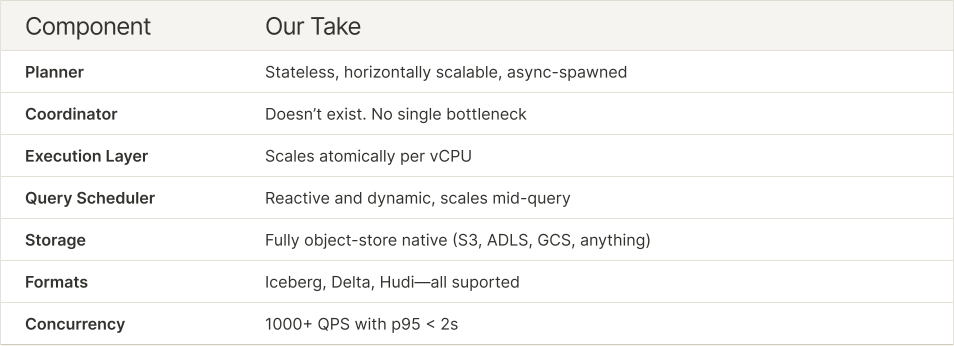
Core Shifts We Made So Far:
1. Disaggregation of internals
- Separate the planner, metadata ops, and workers.
- Each scales independently, not as a monolith.
2. Dynamic, mid-query scaling
- Queries can scale up/down during execution.
- No pre-provisioning for worst-case. Just-in-time compute.
3. Push-based vectorized execution
- We’re similar to DuckDB/Photon but go deeper on compute orchestration.
- Useful when dealing with 1k+ concurrent user-facing queries.
4. No opinionated stack
- Bring your own catalog, governance layer, and format.
- Plug in; don’t port over.
Feature
e6data
Legacy Engines
Scaling granularity
per-vCPU + component-aware
Full-cluster step scaling
Planner architecture
Stateless, elastic
Single-node driver / coordinator
Supported formats
Iceberg, Delta, Hudi (interoperable)
Often proprietary / locked-in
Cost-performance scaling
Linear with load
Non-linear + overprovisioning
Why It Matters
Cost: We run 1000 QPS workloads at ~60% lower TCO than other engines.
Latency: p95 under 2s, even with mixed workloads.
No Lock-In: Use Iceberg today. Switch to Delta tomorrow. Doesn’t matter to us.
Infra Reuse: Already on Kubernetes? Cool. We sit inside that.
Where We’re Headed
Real-time ingest → queryable in <15s from object storage
Vector + SQL → cosine similarity inside SQL filters
AI-native enhancements → smart partitioning, query rewriting, and auto-guardrails
Frequently asked questions
How does e6data's "atomic" architecture cut infrastructure costs?
The engine can scale by just one vCPU instead of doubling whole clusters. This fine-grained, component-aware scaling means teams provision exactly what the workload needs, delivering roughly 60 % lower total cost of ownership on 1,000-QPS benchmarks.
What problem with current decoupled storage-compute setups is e6data addressing?
Most warehouses still force you to scale the entire cluster when a few ad-hoc queries spike, and slow schedulers cause permanent over-provisioning. e6data reacts in real time so the baseline isn’t dictated by the loudest 10% of queries.
Which table formats does e6data support out of the box?
Iceberg, Delta, and Hudi are all first-class citizens, and you can plug in your own catalog or governance layer without lock-in.
Why is push-based vectorized execution important for high concurrency?
It streams columnar data batches through operators, reducing task hand-offs. Together with orchestration tweaks, it keeps performance predictable even with 1,000+ concurrent user-facing queries.